Abstract
Attention mechanisms are widely used in current encoder/decoder frameworks of image captioning, where a weighted average on encoded vectors is generated at each time step to guide the caption decoding process. However, the decoder has little idea of whether or how well the attended vector and the given attention query are related, which could make the decoder give misled results. In this paper, we propose an Attention on Attention (AoA) module, which extends the conventional attention mechanisms to determine the relevance between attention results and queries. AoA first generates an information vector and an attention gate using the attention result and the current context, then adds another attention by applying element-wise multiplication to them and finally obtains the attended information, the expected useful knowledge. We apply AoA to both the encoder and the decoder of our image captioning model, which we name as AoA Network (AoANet). Experiments show that AoANet outperforms all previously published methods and achieves a new state-of-the-art performance of 129.8 CIDEr-D score on MS COCO Karpathy offline test split and 129.6 CIDEr-D (C40) score on the official online testing server.
Results
Method
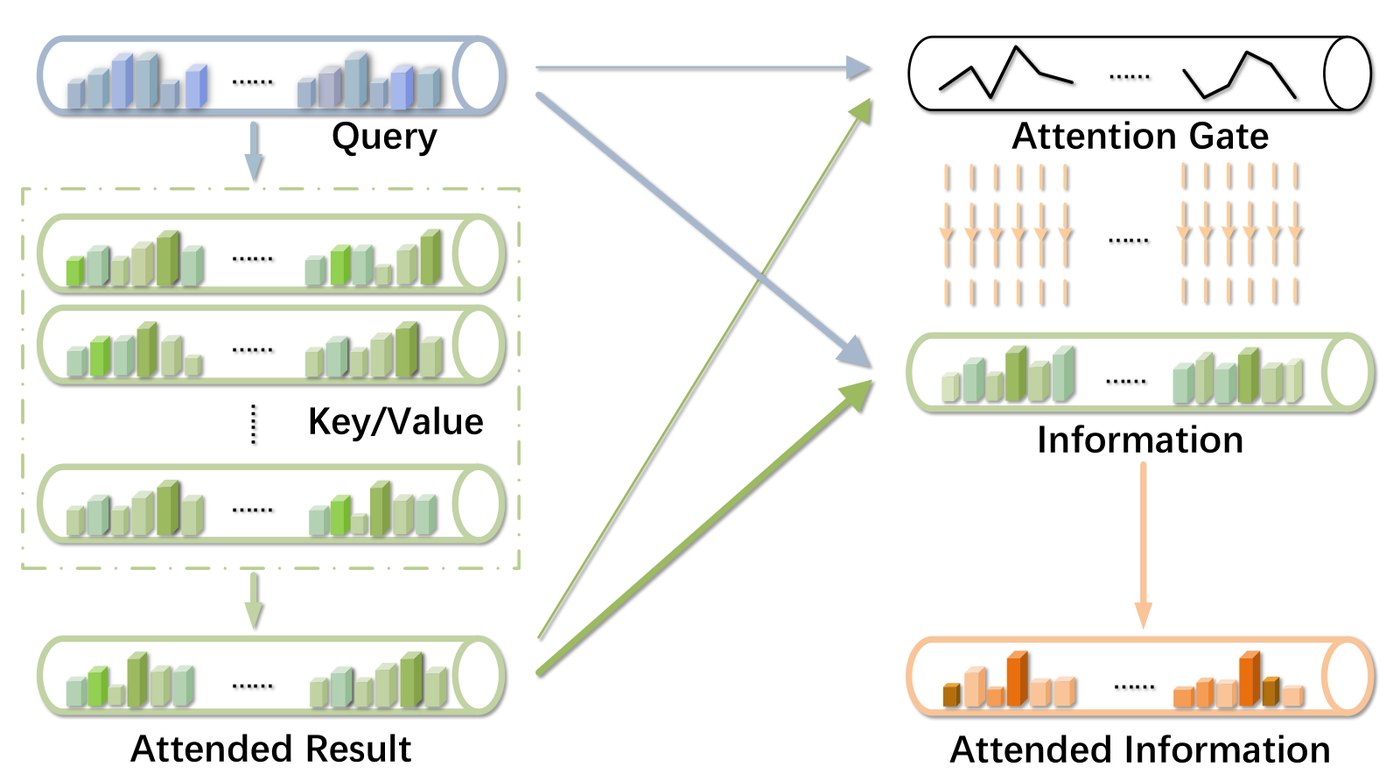
AoA module. The attended result and the query produce an information vector and an attention gate. Their element-wise product is the attended information.
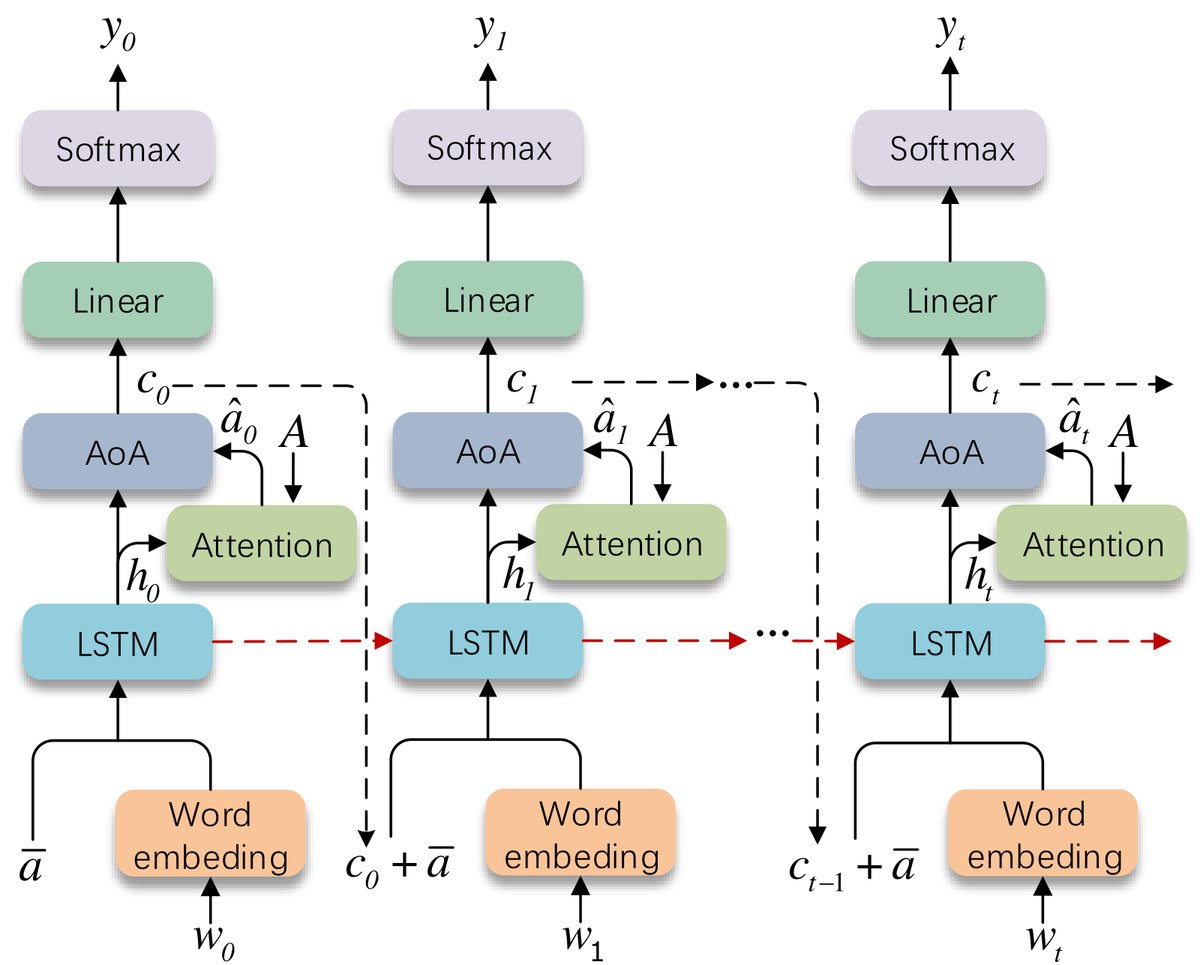
Decoder. At each step an LSTM state queries the image features, and AoA refines the attended context before word prediction.
BibTeX
@inproceedings{huang2019attention,
  title     = {Attention on Attention for Image Captioning},
  author    = {Huang, Lun and Wang, Wenmin and Chen, Jie and Wei, Xiao-Yong},
  booktitle = {Proceedings of the IEEE/CVF International Conference on Computer Vision (ICCV)},
  pages     = {4634--4643},
  year      = {2019}
}