Abstract
Generating videos from text is a challenging task due to its high computational requirements for training and infinite possible answers for evaluation. Existing works typically experiment on simple or small datasets, where the generalization ability is quite limited. In this work, we propose GODIVA, an open-domain text-to-video pretrained model that can generate videos from text in an auto-regressive manner using a three-dimensional sparse attention mechanism. We pretrain our model on HowTo100M, a large-scale text-video dataset that contains more than 136 million text-video pairs. Experiments show that GODIVA not only can be fine-tuned on downstream video generation tasks, but also has a good zero-shot capability on unseen texts. We also propose a new metric called Relative Matching (RM) to automatically evaluate the video generation quality. Several challenges are listed and discussed as future work.
3D Sparse Attention
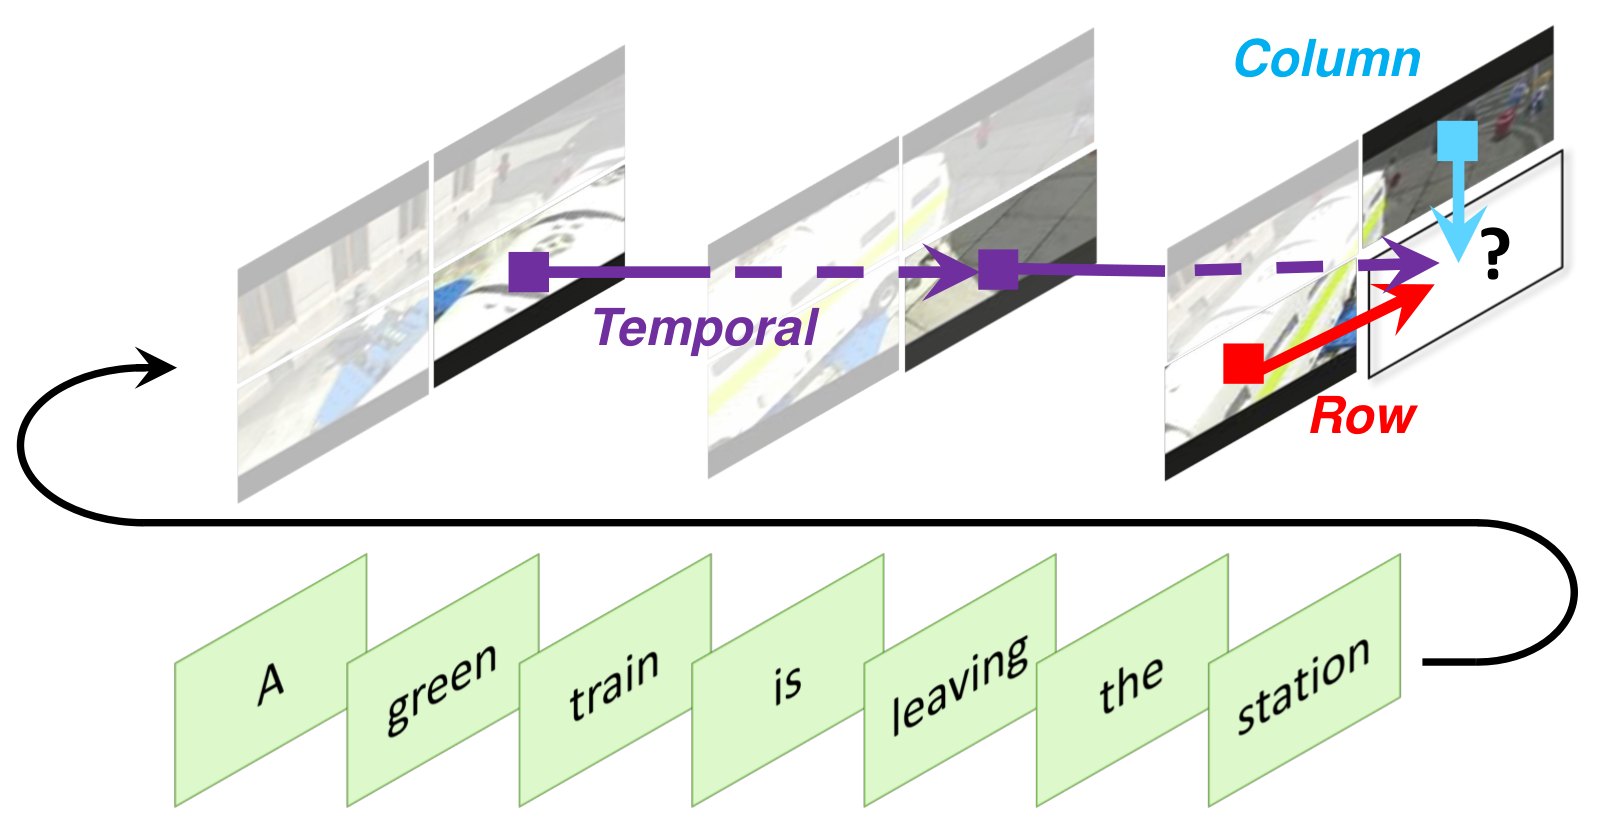
Each new visual token attends along its row, its column, and the temporal axis, rather than to every previous token.
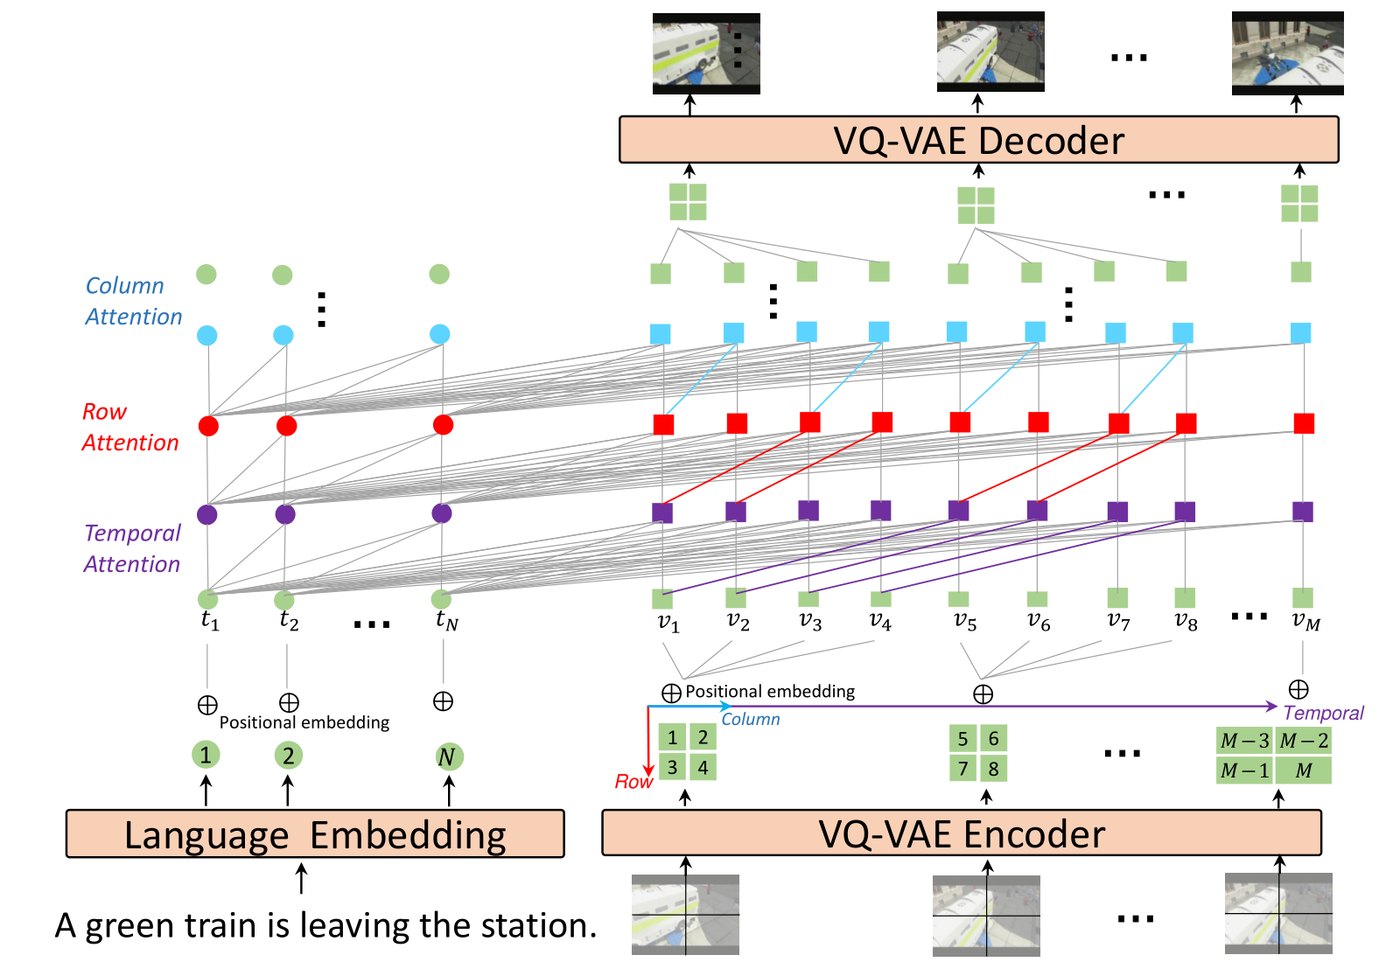
Architecture. Text is embedded and VQ-VAE-encoded frames are flattened into a token sequence. Stacked temporal, row, and column attention layers predict the next video tokens, which the VQ-VAE decoder turns back into frames.
Highlights
BibTeX
@article{wu2021godiva,
  title   = {GODIVA: Generating Open-DomaIn Videos from nAtural Descriptions},
  author  = {Wu, Chenfei and Huang, Lun and Zhang, Qianxi and Li, Binyang and Ji, Lei and Yang, Fan and Sapiro, Guillermo and Duan, Nan},
  journal = {arXiv preprint arXiv:2104.14806},
  year    = {2021}
}