Results
Abstract
Diffusion Transformers have demonstrated remarkable capabilities in visual synthesis, yet they often struggle with high-level semantic reasoning and long-horizon planning. This limitation frequently leads to visual hallucinations and mis-alignments with user instructions, especially in scenarios involving complex scene understanding, human-object interactions, multi-stage actions, and in-context motion reasoning. To address these challenges, we propose Plan-X, a framework that explicitly enforces high-level semantic planning to instruct video generation process. At its core lies a Semantic Planner, a learnable multimodal language model that reasons over the user's intent from both text prompts and visual context, and autoregressively generates a sequence of text-grounded spatio-temporal semantic tokens. These semantic tokens, complementary to high-level text prompt guidance, serve as structured “semantic sketches” over time for the video diffusion model, which has its strength at synthesizing high-fidelity visual details. Plan-X effectively integrates the strength of language models in multimodal in-context reasoning and planning, together with the strength of diffusion models in photorealistic video synthesis. Extensive experiments demonstrate that our framework substantially reduces visual hallucinations and enables fine-grained, instruction-aligned video generation consistent with multimodal context.
Method
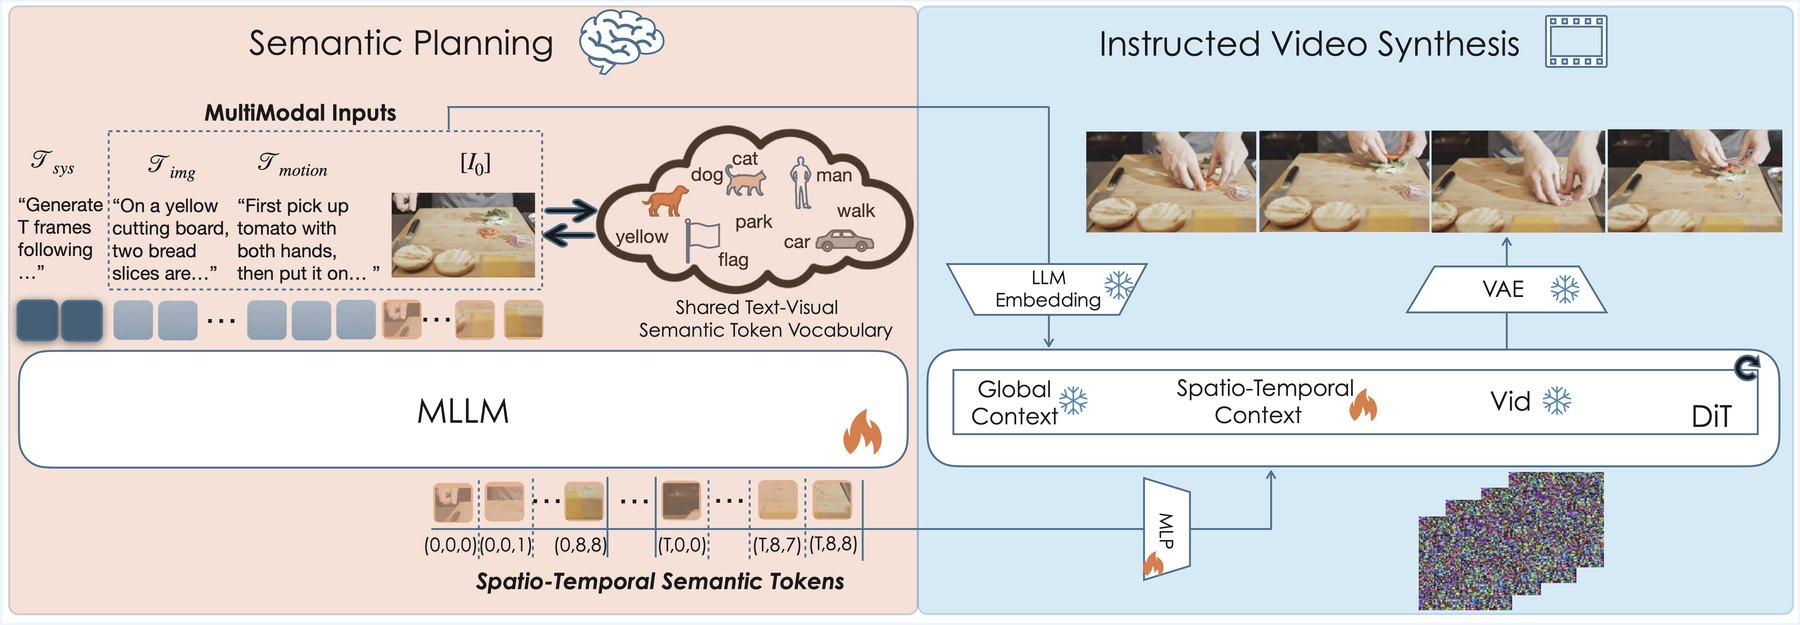
Overview. The Semantic Planner (an MLLM) takes the scene prompt, the motion description, a system prompt that sets the number of target frames, and optionally the encoded first frame. It autoregressively emits text-aligned semantic tokens that encode keyframe-level spatio-temporal structure. A dedicated semantic guidance branch with 3D spatio-temporal RoPE feeds these tokens to a pretrained DiT, which renders a temporally coherent video.
Base DiT vs. Plan-X
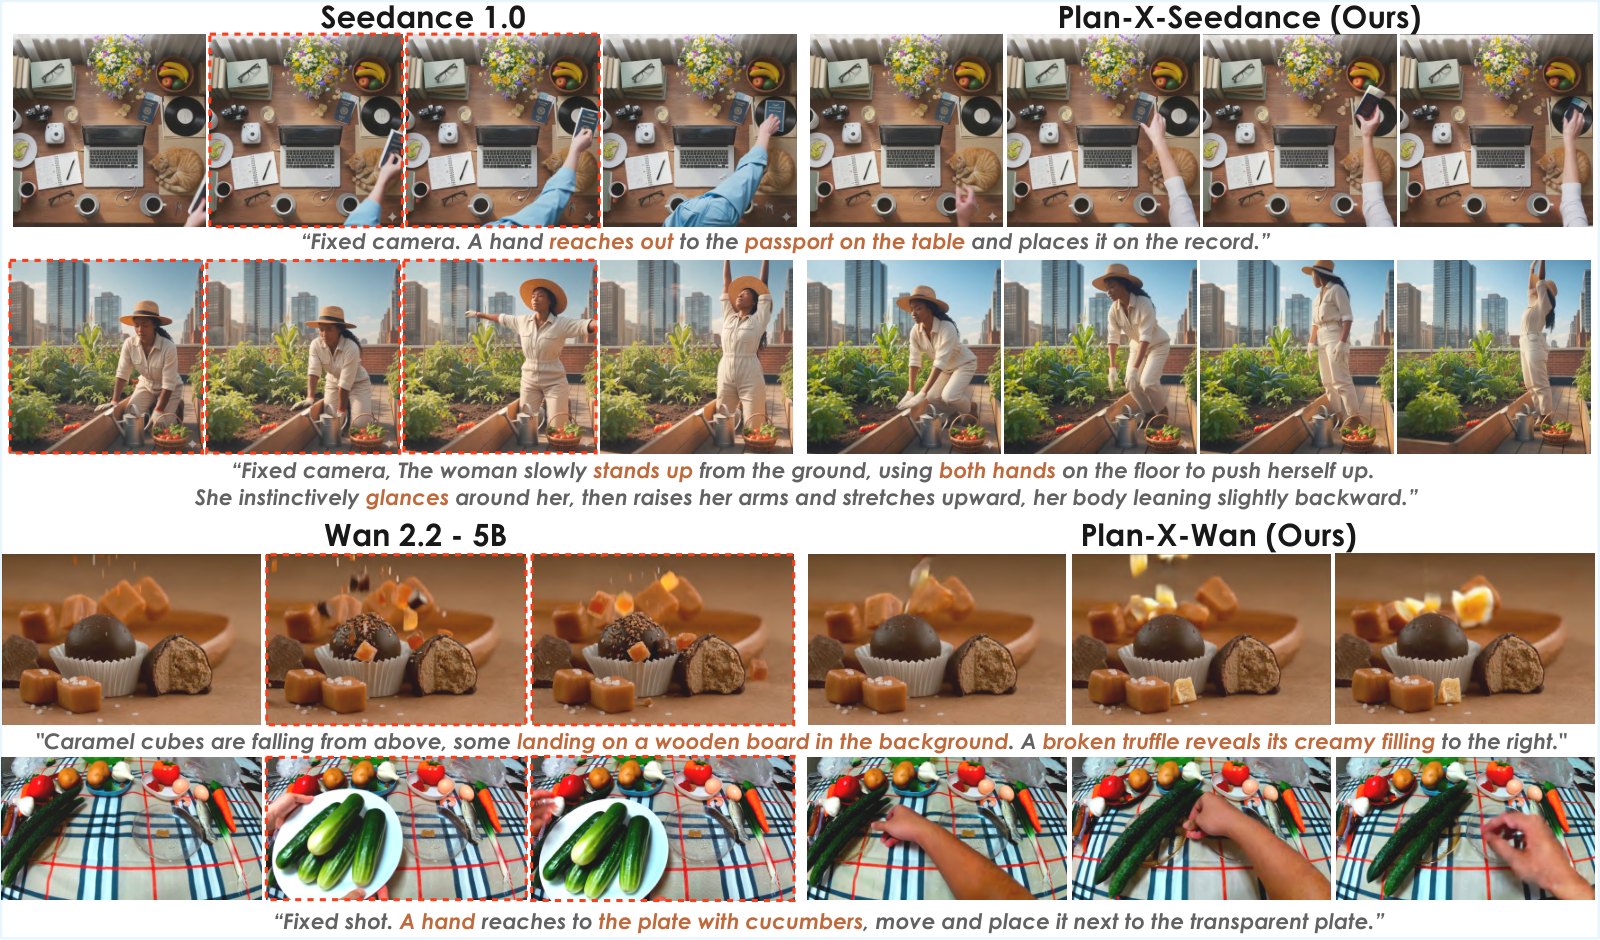
Keyframes from the paper: Plan-X stays faithful to multi-step, interaction-heavy prompts where the base models drift or hallucinate.
More comparisons, ablations, and applications are on the project page →
BibTeX
@article{huang2025planx,
  title   = {Plan-X: Instruct Video Generation via Semantic Planning},
  author  = {Huang, Lun and Xie, You and Xu, Hongyi and Gu, Tianpei and Zhang, Chenxu and Song, Guoxian and Li, Zenan and Zhao, Xiaochen and Luo, Linjie and Sapiro, Guillermo},
  journal = {arXiv preprint arXiv:2511.17986},
  year    = {2025}
}